The problem
Large language models can produce fluent answers that include claims unsupported by the available evidence. Detecting these errors is more difficult than flagging an obviously incorrect sentence: an answer may combine grounded statements with a small number of fabricated or misleading details.
Research question and approach
This project compares eight hallucination-detection approaches using a benchmark of 200 cases, including both grounded and hallucinated examples. The evaluation considers how a method checks claims against available source material and how reliably it separates supported from unsupported content.
A central idea is source-grounded consistency: rather than trusting the apparent confidence of a generated answer, examine whether specific claims are supported by the supplied evidence. The broader comparison includes more lightweight approaches and methods that use explicit grounding.
Evaluation and results
The best-performing method reached 90.5% accuracy on the 200-case research benchmark. This is a result for that experimental setup, not a guarantee on arbitrary tasks, languages or real-world deployments. The results also motivate looking at performance by task type and failure mode rather than a single headline accuracy number.
Engineering implementation
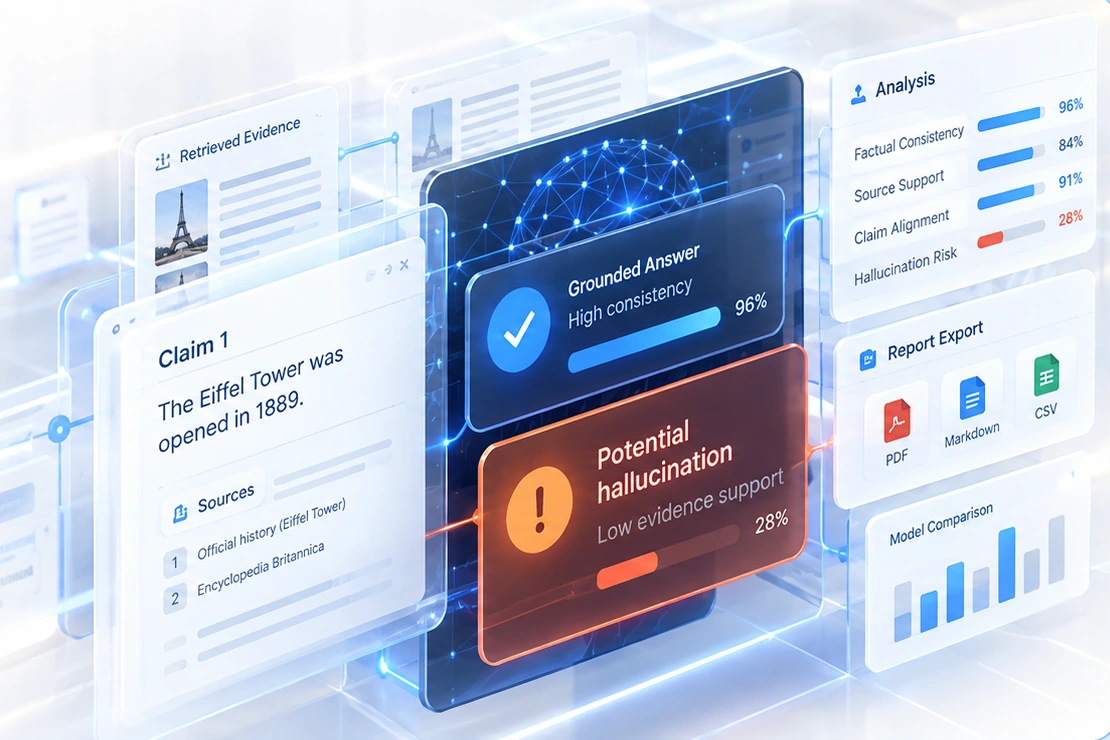
Alongside the study, the project includes a research dashboard for exploring detector workflows, retrieved evidence, claim-level findings and citations, with options to export an analysis report. The software makes it easier to inspect why a claim was flagged rather than treating the detector as an opaque verdict.
Limitations and next steps
Hallucination detection depends on the quality and completeness of evidence and on the kinds of questions represented in the evaluation set. A detector may struggle with missing context, ambiguous claims or conflicting sources. Future research would benefit from larger, more diverse datasets, calibrated abstention, and cost-aware comparisons under matched inference budgets.